How Edge8 coaches a 27-person team on a 14-day rhythm with one human decision per 1-1
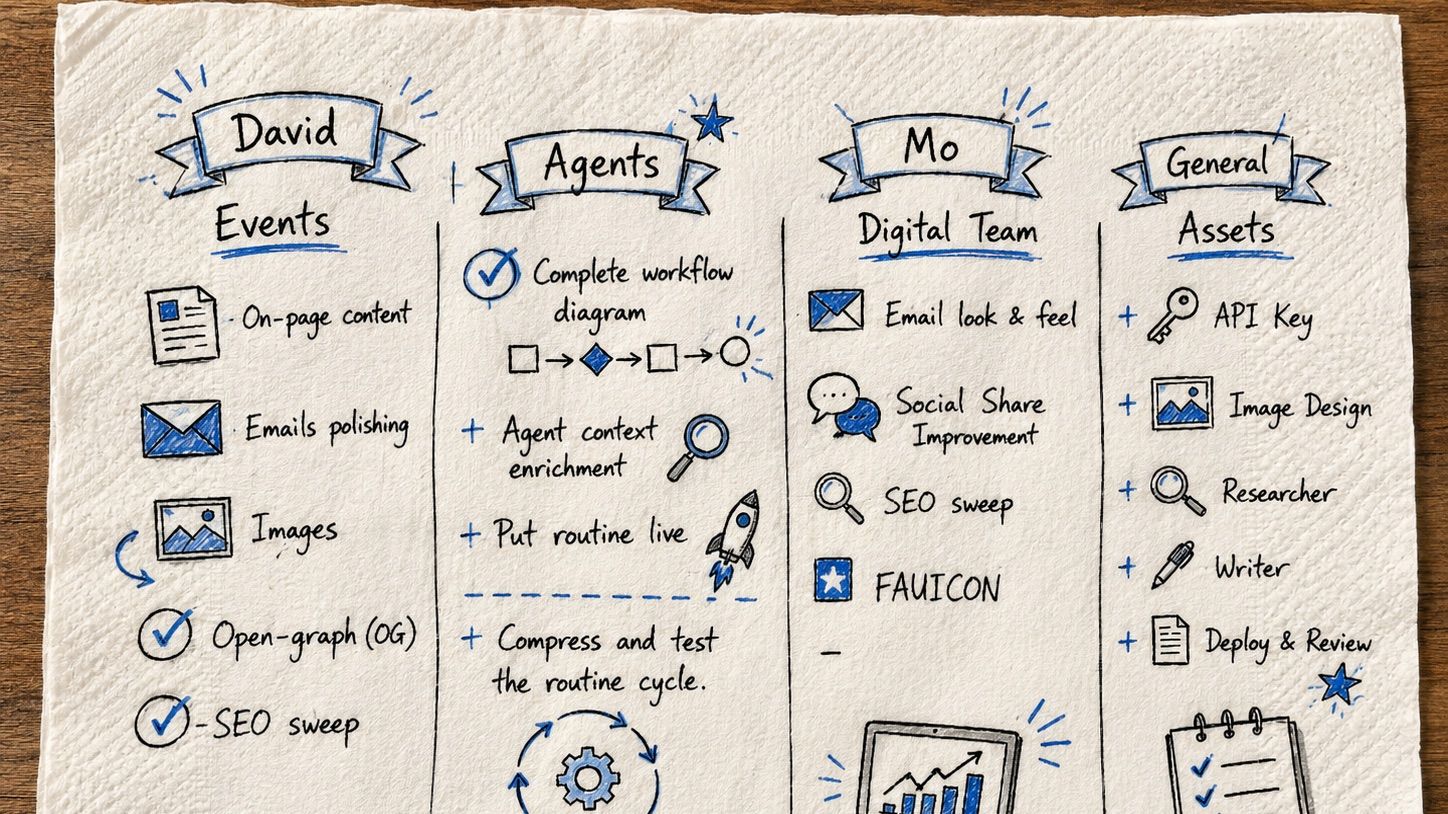
Coaching cadence. Nobody books the next 1-1; the system rolls it forward.
Human decision per 1-1: the coach reads the AI draft and publishes it.
Performance reviews on record, scored on 11 anchored dimensions, five of them AI craft.
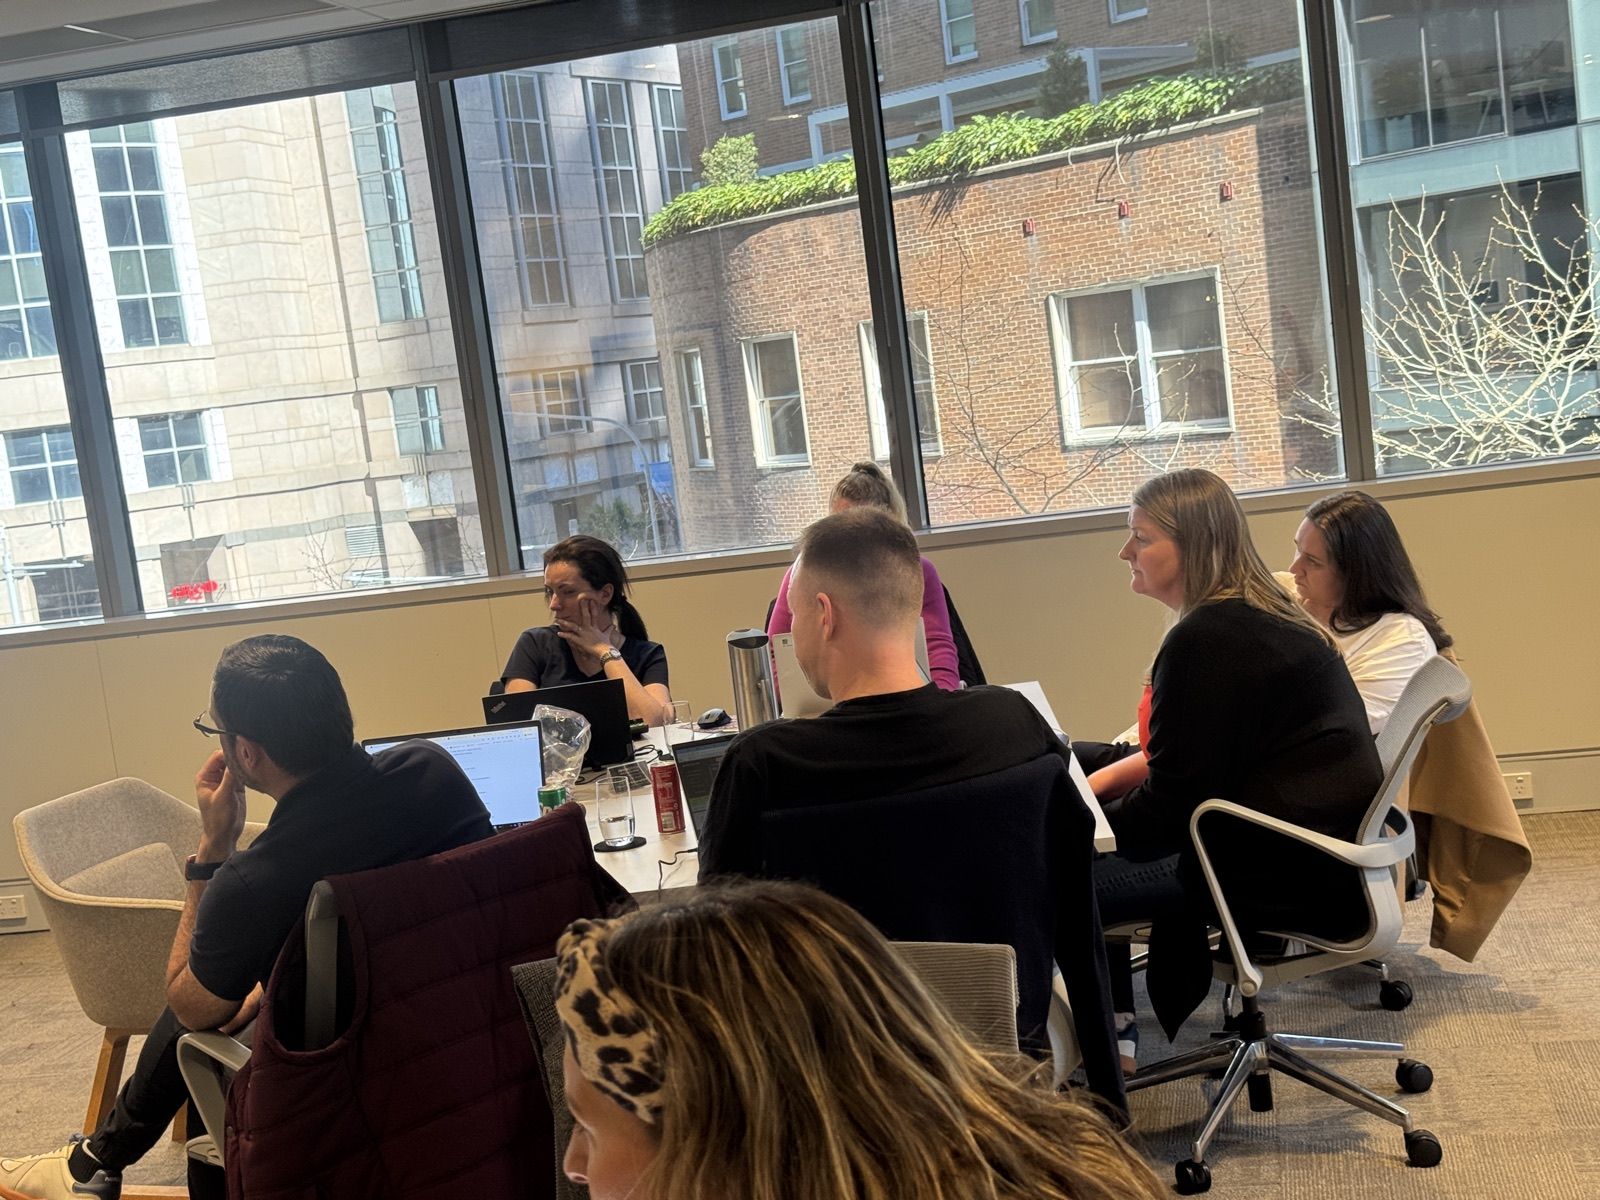
Edge8 is a distributed team, and for years its coaching lived in the coach's head, a few documents, and review forms nobody reopened. In July 2026 we moved the whole rhythm onto our own database: the next 1-1 schedules itself, the prep writes itself from what the person committed to, the recap drafts itself from the transcript, and commitments come back as buttons in Lark. In September we measured it, found the parts that did nothing, and deleted them.
A coach with five people on a two-week cadence spends about an hour per person per cycle on prep and recap. That is roughly 130 hours a year before anyone is coached. So the prep got skipped, the recap got shortened, and the commitments made in one 1-1 were rarely on the table at the next.
Reviews had the same problem in a different costume. Thirty-three historical reviews sat in forms nobody reopened, self and manager pairs existed for only five of 27 people, and the average rating was 4.1 with no 1s, which tells you the instrument was measuring politeness.
“I used to walk into a 1-1 with whatever I could remember from last time. The person on the other side always remembered more than I did, and they could tell.”
Dave Hajdu, founder
The team studies the program we sell.
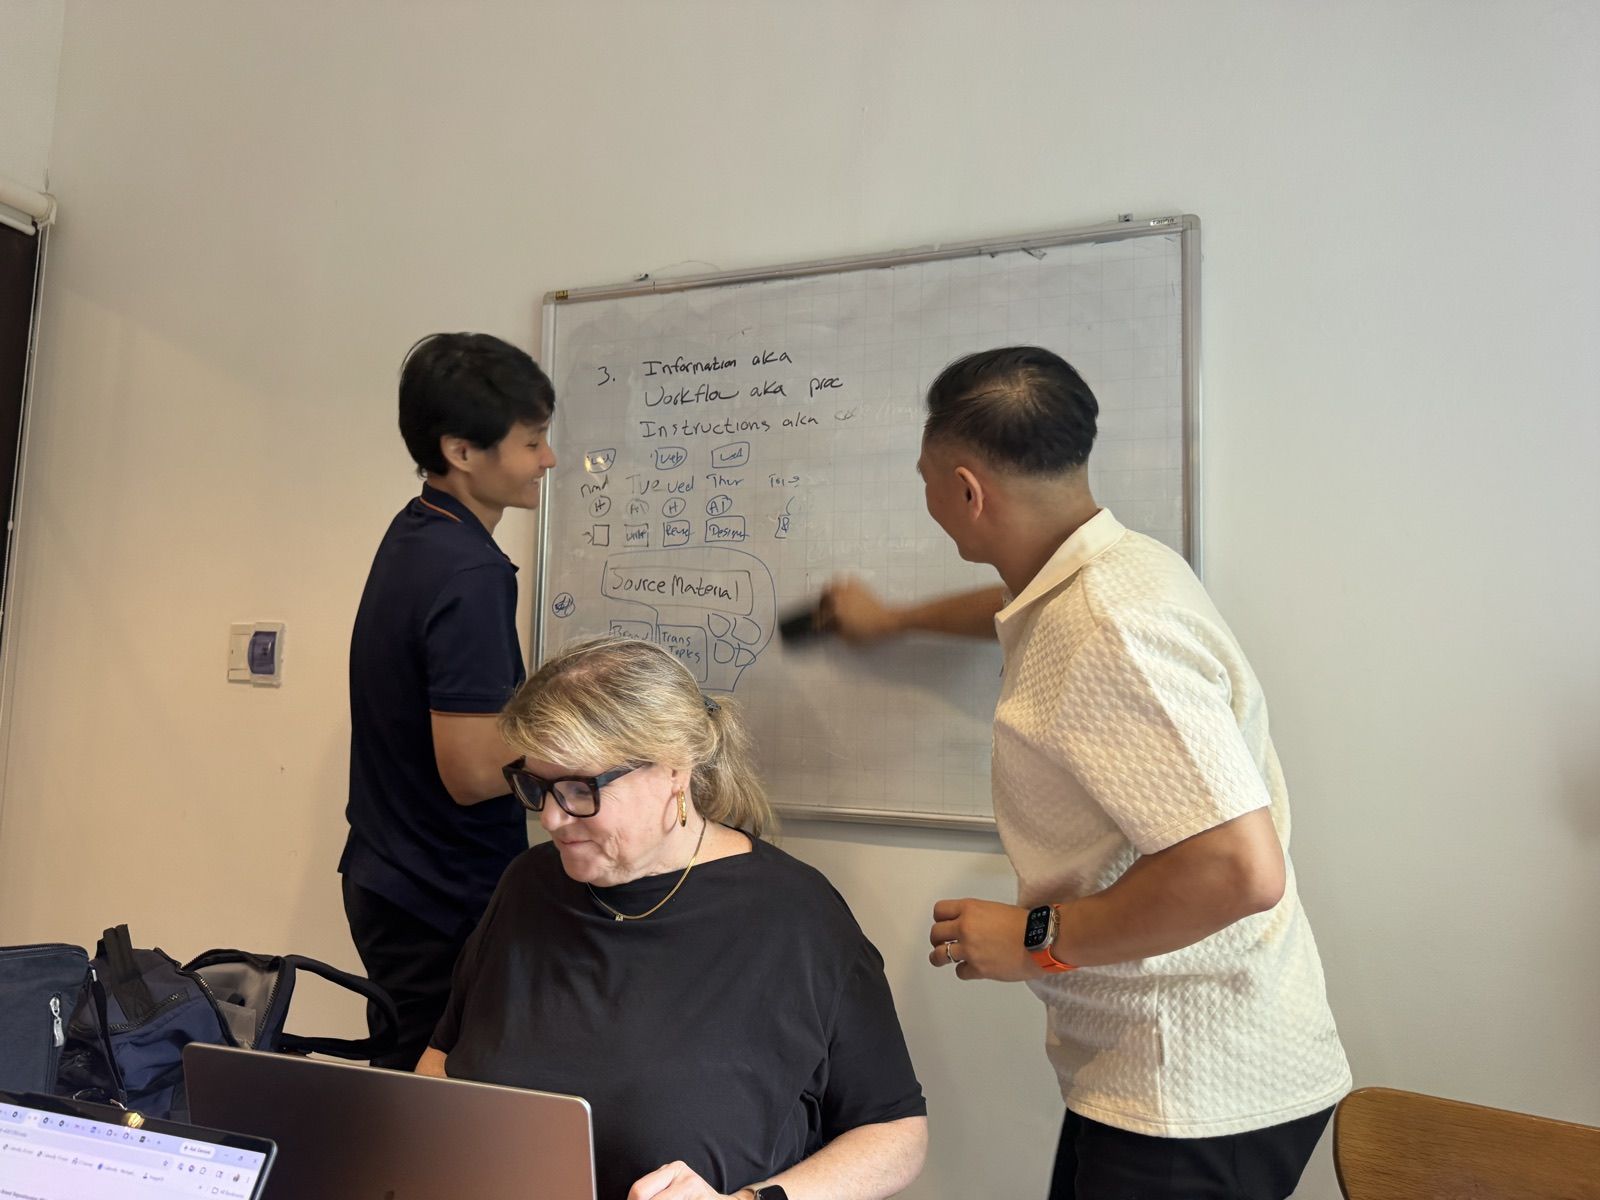
Fourteen of the team are in the AI Officer Institute program, with 64 missions and 17 electives completed between them. It is why five of the eleven review dimensions are AI craft: planning, workflow design, organizing information, creating instructions and building. You cannot coach what you do not teach, and you cannot review what you never defined.
- The cadence rolls itself. Every coached person has a coach, who can differ from the manager, and a cadence, default 14 days. A daily routine steps the date forward from the last 1-1 and nudges weekends to Monday. To stop it, the coach pauses it. Nobody books a meeting.
- Prep is ten bullets, and the first one is the goal. Four days out, Claude writes the prep from open commitments, FAST Goals, the talking points either side added, and what the last recap covered. The coach gets it in Lark; the person gets the same list minus the coach-only lines.
- The recap drafts itself, the coach publishes it. Lark records and transcribes. An hourly routine matches the transcript to the 1-1 and writes two tiers: a private note for the coach and a shared recap in the person's own language, with commitments as first-person promises and one verbatim quote per claim of progress. Publishing is the one human gate.
- Commitments come back as buttons. On publish, the person gets one Lark card: what we covered in five lines, then each commitment with Done, Blocked, Still on it. A tap writes the status. Blocked messages the coach. Mid-cycle the same card returns with only what is still open.
- Built in Claude Code, with the model matched to the job. Our engineers build in Claude Code. At runtime one registry names four tiers: Claude Haiku 4.5 for fast operational work, Sonnet 5 as the standard, Opus 5 reserved for work that provably needs it, and Fable 5.1 where the output is the product. Prep runs on Sonnet. The recap has to read a whole transcript and keep a promise in the speaker's own words, so it runs on Opus. That is why the loop costs a couple of dollars a month, and why a model upgrade is a one-line change.
- Reviews fire on three dates. Probation at six weeks, mid-year at five months, renewal a month before contract end. Self-assessment first; the manager drafts blind. Eleven anchored dimensions, five of them AI craft, with expected scores by level. External reviewers get a signed link, and a review call's transcript is summarized into a labelled section that never overwrites the manager's words.
- 31 one-on-ones on the record since March 2026, 27 held, 11 of them in August alone. 21 of the 27 carry a transcript.
- 69 commitments tracked in one ledger: 19 completed, 41 open, 2 blocked, 2 dropped. Before, that number was zero, because there was no ledger.
- 68 reviews on record for 27 people, with decisions attached: 18 continue to contract, 3 promotions, 2 renew with changes, 1 extend probation.
- Prep takes two minutes to read. Prep and recap went from roughly an hour per person per cycle to the time it takes to read and press publish.
Our September read of production found the daily routine crashing five days out of six, 10 check-ins sent and none that changed anything, and 11 of 27 held 1-1s with no recap. We deleted the check-in essay, moved it to a template card, and fixed the routine. If you cannot see your coaching system's failure rate, you do not have one.
A 1-1 that opens with the goal spends the hour on the goal. A 1-1 that opens with "how are things" spends it on things.
The moment pay is in the room, the ratings are negotiated, not observed. Freeze the instrument, anchor every dimension, and tell people the expected score for their level.
This runs on the same Company OS we install for clients. If you want the people who built it inside your company, talk to us about the roles you actually need.